AI Model Monitoring in CRM: How to Detect When Automated Decisions Start Losing Accuracy
Model evaluation does not end when an AI feature goes live. CRM environments change continuously: new products launch, territories move, sales stages are redesigned, customer behavior shifts, integrations fail, and employees adapt to the recommendations they receive. A model trained on yesterday’s operating environment can become less accurate or less useful even when the software itself is functioning normally.
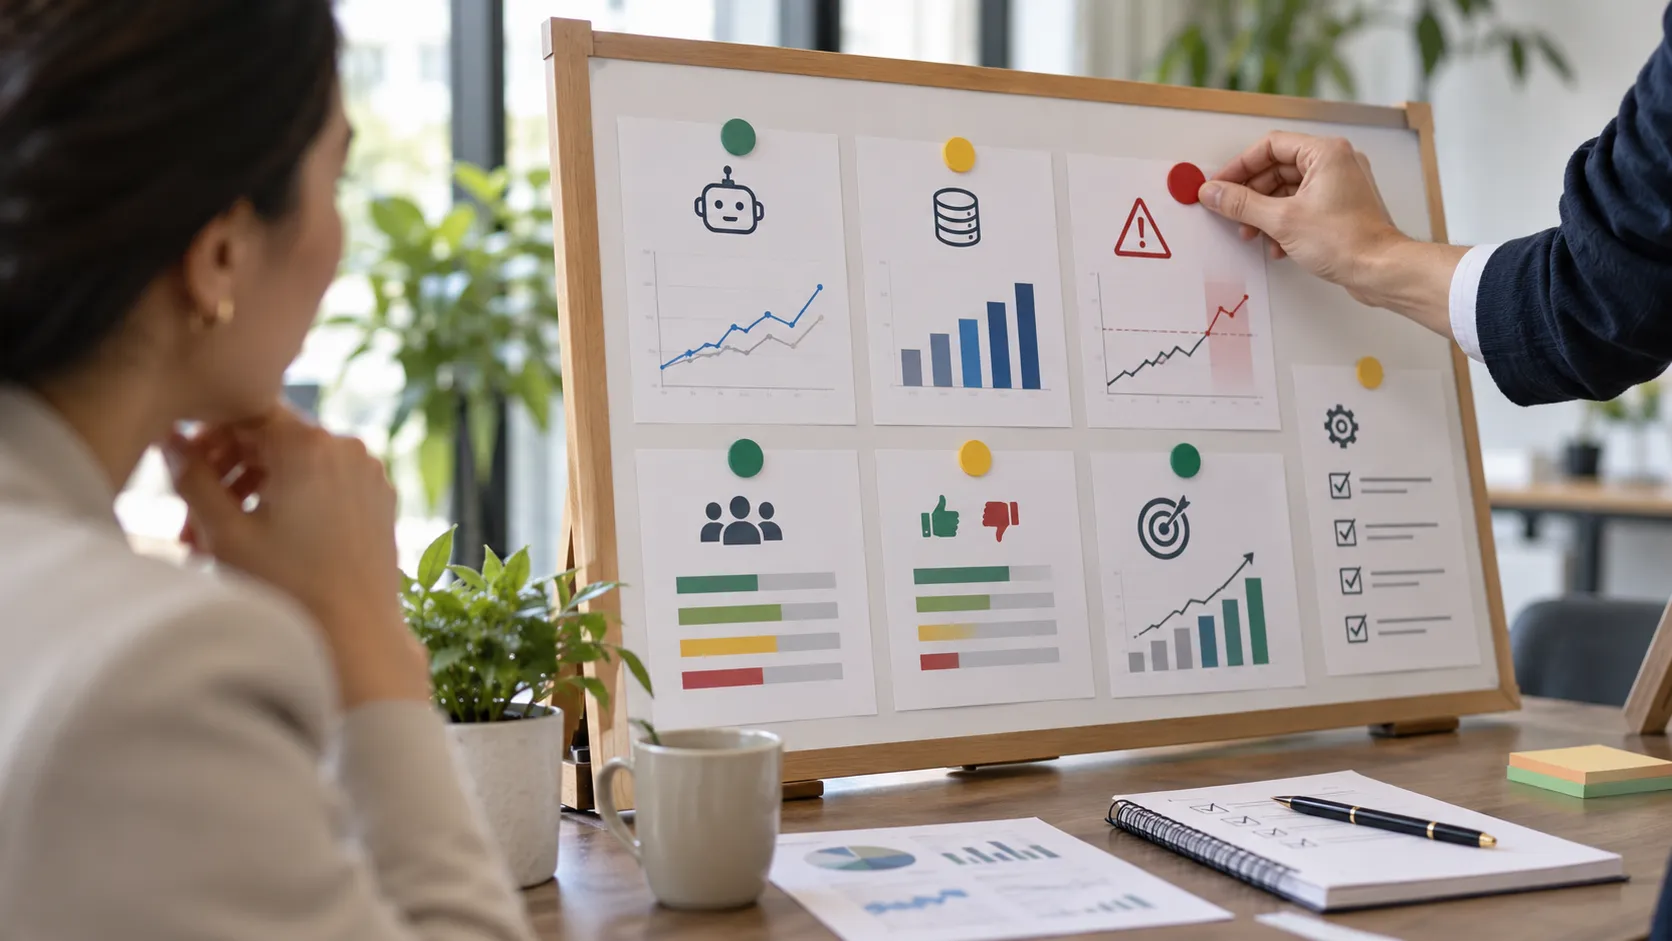
AI model monitoring is the operating discipline that detects those changes early enough to respond. It combines technical performance, data quality, workflow outcomes, segment analysis, and human feedback. The goal is not to watch every metric constantly, but to define signals that reveal when trust in the model should be reconsidered.
Key Takeaways
Monitor the business decision and customer outcome, not only technical model metrics.
Data drift, concept drift, process changes, and feedback loops can all reduce model value.
Performance should be checked across relevant customer and operational segments.
Human overrides and corrections are important monitoring signals.
Every production AI use case needs thresholds, owners, and a response plan when performance deteriorates.
Know What Can Drift
Input drift occurs when the distribution of data changes: average deal size rises, a new product creates different usage patterns, or a field starts being populated by a new integration. Concept drift occurs when the relationship between inputs and outcomes changes, such as when customer behavior shifts after a pricing change.
Operational drift matters too. A team may change how it uses stages or respond differently because the model influences attention. Monitoring should therefore include the process around the model, not only the model artifact.
Establish a Deployment Baseline
Before launch, record performance by time period, segment, and use case. Also capture data completeness, output distribution, override rate, latency, failure rate, and relevant business outcomes. Without a baseline, teams can notice that a metric changed without knowing whether the change is meaningful.
A baseline should reflect production-like data and real user behavior where possible. Laboratory evaluation alone may miss integration delays, missing fields, and workflow exceptions.
Monitor Outcomes With the Right Delay
Some outcomes are available quickly, while others take months. A lead-ranking model may receive short-term engagement feedback in days but final revenue outcomes much later. Use leading operational indicators without pretending they replace the eventual business result.
Create a monitoring calendar that acknowledges outcome delay. Otherwise teams may overreact to noisy early proxies or wait too long to notice serious deterioration.
Segment Performance
Overall accuracy can remain stable while performance deteriorates for a region, product, customer type, channel, or newly introduced process. Segment monitoring is especially important when groups have different data coverage or behavior.
Choose segments that reflect business risk and known variation. Too many slices create noise, but one company-wide metric can hide meaningful failures.
Use Human Behavior as a Signal
A sudden increase in overrides, ignored recommendations, manual corrections, or user complaints may indicate a problem before outcome labels are available. Capture structured reasons where practical so monitoring can distinguish model error from missing data, policy changes, or unusual customer context.
Do not assume that lower acceptance automatically means the model became worse. Users can also change incentives or develop workarounds. Investigate the pattern.
Define What Happens When a Threshold Is Crossed
Monitoring without a response plan creates dashboards rather than control. Define who reviews an alert, what evidence is needed, whether the model should be limited to advisory use, when retraining is justified, and when the feature should be paused.
Some failures can be fixed through data or workflow corrections rather than retraining. The response should match the cause instead of treating every performance decline as a modeling problem.
A Practical Model-Monitoring Scenario
A lead-scoring model performs well for six months. Then the company launches a self-service trial that creates a large new source of leads. Overall conversion remains stable, but the model’s top decile converts much worse for the new trial segment because the historical training data contained almost no comparable behavior.
Segment monitoring identifies the issue even though the company-wide metric looks acceptable. The team temporarily limits score-based routing for trial leads, collects new outcomes, and develops separate evaluation for that source. The incident also leads to a change-management rule: major source or product changes must be reviewed for potential model impact before launch.
A Practical CRM AI Monitoring Stack
Layer What to Watch Example Response
Data Missingness, ranges, category shifts, source changes. Investigate integration or process change.
Model output Score distribution, confidence, recommendation mix. Check for drift or unexpected concentration.
Human interaction Overrides, corrections, ignores, complaints. Review reasons and affected segments.
Business outcome Conversion, retention, resolution, value, cost. Compare with baseline or control.
Risk and operations Failures, latency, access errors, harmful actions. Pause or restrict the feature when thresholds are exceeded.
Common Mistakes to Avoid
Monitoring only one accuracy metric
A single aggregate metric can hide data failures, segment deterioration, or poor business outcomes. Use a layered view.
Retraining automatically whenever data changes
Not every change harms the model, and automatic retraining can introduce new problems. Investigate the cause and re-evaluate before replacing a production model.
Ignoring product and process changes
CRM models live inside operating systems. New fields, incentives, routing rules, and products can change the meaning of historical patterns.
What to Do Next
Document the production baseline for model, data, user behavior, and business outcomes.
Choose a small set of relevant customer and operational segments for performance review.
Define leading indicators while waiting for delayed outcome labels.
Capture override and correction reasons where human review exists.
Set thresholds and name the person responsible for investigating each type of alert.
Create response options such as data repair, scope restriction, rule adjustment, retraining, or temporary pause.
Continue Reading on Clientira
Related Clientira guides provide additional context:
AI Data Readiness for CRM: How to Know Whether Your Customer Data Is Ready
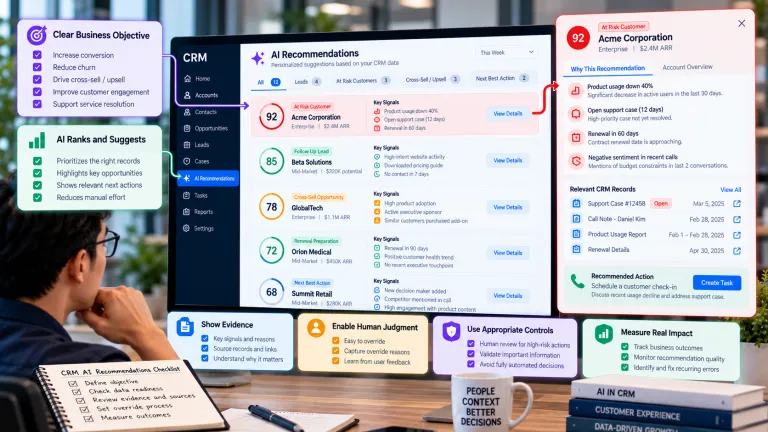
AI Recommendation Systems in CRM: When Suggestions Help and When Humans Should Override Them
AI Opportunity Scoring in CRM: How to Prioritize Deals Without Blindly Trusting the Model
Frequently Asked Questions
What is model drift in CRM?
Model drift broadly describes deterioration that occurs when production data or the relationship between data and outcomes changes compared with the environment in which the model was evaluated.
How often should CRM AI models be monitored?
Monitoring frequency should match how quickly inputs and decisions can change. High-volume or high-impact systems may need continuous technical monitoring plus regular outcome review, while slower use cases can use a less frequent cadence.
Does every performance drop require retraining?
No. The cause may be an integration failure, field-definition change, workflow change, unusual cohort, or user behavior. Diagnose first, then choose the appropriate response.
Why track human overrides?
Overrides can reveal missing context, data errors, model weaknesses, or changing business rules. Structured override reasons are a valuable early-warning and learning signal.
Final Thoughts
AI models in CRM operate in environments that never stay still. Monitoring is what turns a successful pilot into a sustainable capability by revealing when data, behavior, or business context has moved beyond the model’s assumptions.
Build monitoring around the decision the model supports. Watch data, outputs, human responses, outcomes, and risk together, and decide in advance what the organization will do when confidence falls. That makes AI operations more resilient than waiting for users or customers to discover the problem first.